Same questions, three decision systems — fly connectome on a $350 laptop vs Jev vs Laya
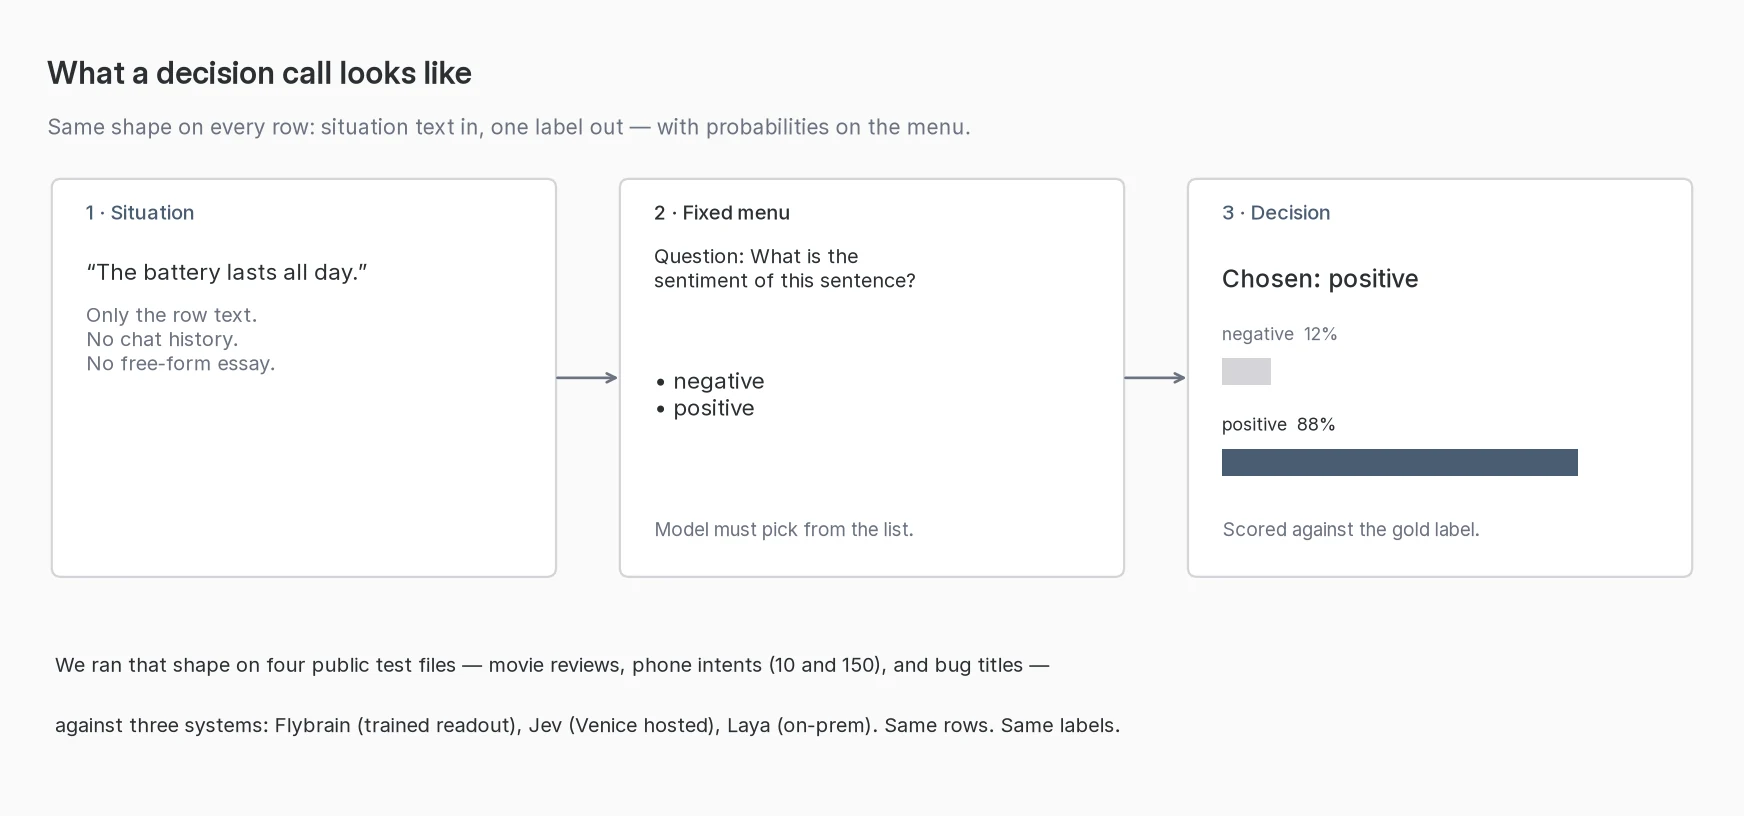
Everybody’s losing their minds over Jev right now. Fair enough — it’s a real decision model, not another chat bot that hands you an essay and makes you do the deciding. Situation in. Fixed menu out. Probabilities on every option. You can score that. You can time that.
So I put it on the same frozen public benches as two other systems and ran the whole thing. Same questions. Same rows. Same labels.
- Jev — Venice’s hosted
jev-latest. Out of the box. We paid tokens and waited on their servers. - Laya — ConvAI’s open weights, on our machine. Also out of the box.
- Flybrain — ours. A readout on the published fruit-fly larva connectome (Winding et al., Science 2023 — about 3,000 neurons, ~117,000 synaptic edges). Not a metaphor. Running on a $350 Lenovo IdeaPad with no GPU.
Accuracy. Sureness. Speed. Cost. Who finished the long bench. That’s the bakeoff.
What we trained — and what we didn’t
Jev: nothing. Cold.
Laya: nothing. We pulled convaiinnovations/laya and ran it. English checkpoint on the short benches. Multilingual with a longer window on the 150-intent menu so it could actually see all 151 options. We deliberately skipped their typed-decisions fine-tune — that’s a different quiz.
Flybrain: a small training pass, and only that. The larva wiring stays frozen — we do not train the graph. Text becomes GloVe vectors, gets injected into that recurrent reservoir, we pool the activity, and on each task’s train split we fit a thin ridge classification head. Leak, steps, radius, inject size, pooling — picked on validation with a fixed grid. Temperature for the probabilities, also validation. Test rows never touched until the final score. So “Flybrain saw the training split” means: sticky note on a locked engine. Not a new engine. Not a transformer fine-tune.
TL;DR for humans who don’t live in this stack: we didn’t rebuild the fly brain. We taught a tiny “which answer from this menu?” layer on practice examples, then checked it on held-out rows it had never practiced on. Jev and Laya never got that practice. That’s the fair caveat. I’m saying it up front.
We’ve already seen the body learn — on a different job
On a separate next-token job we do train connectome weights, not just a readout. Score is “how surprised are you by the real next word?” Lower is better. We always line that up against dumb lookup rulers: a bigram floor (guess from the last word) and a trigram floor (last two). Those aren’t rival products. They’re the “are you even doing anything?” line.
In those labs the trained fly cleared bigram and got close to trigram — still improving when we stopped — and we didn’t push past those epoch caps to finish the climb. So: weight training on this body moves the needle. We do not have a finished “beat trigram” certificate. We left performance on the table.
Which brings us back. This Jev/Laya comparison only used the light recipe. Where Flybrain trails Jev on accuracy is the ceiling of this recipe — not a stress-tested limit for the fly. Pointing the heavier weight-training loop at these decision tasks is the obvious unpaid next experiment. We haven’t run it yet. I’m not going to pretend we have.
The numbers
| Test | Rows | Flybrain | Jev | Laya |
|---|---|---|---|---|
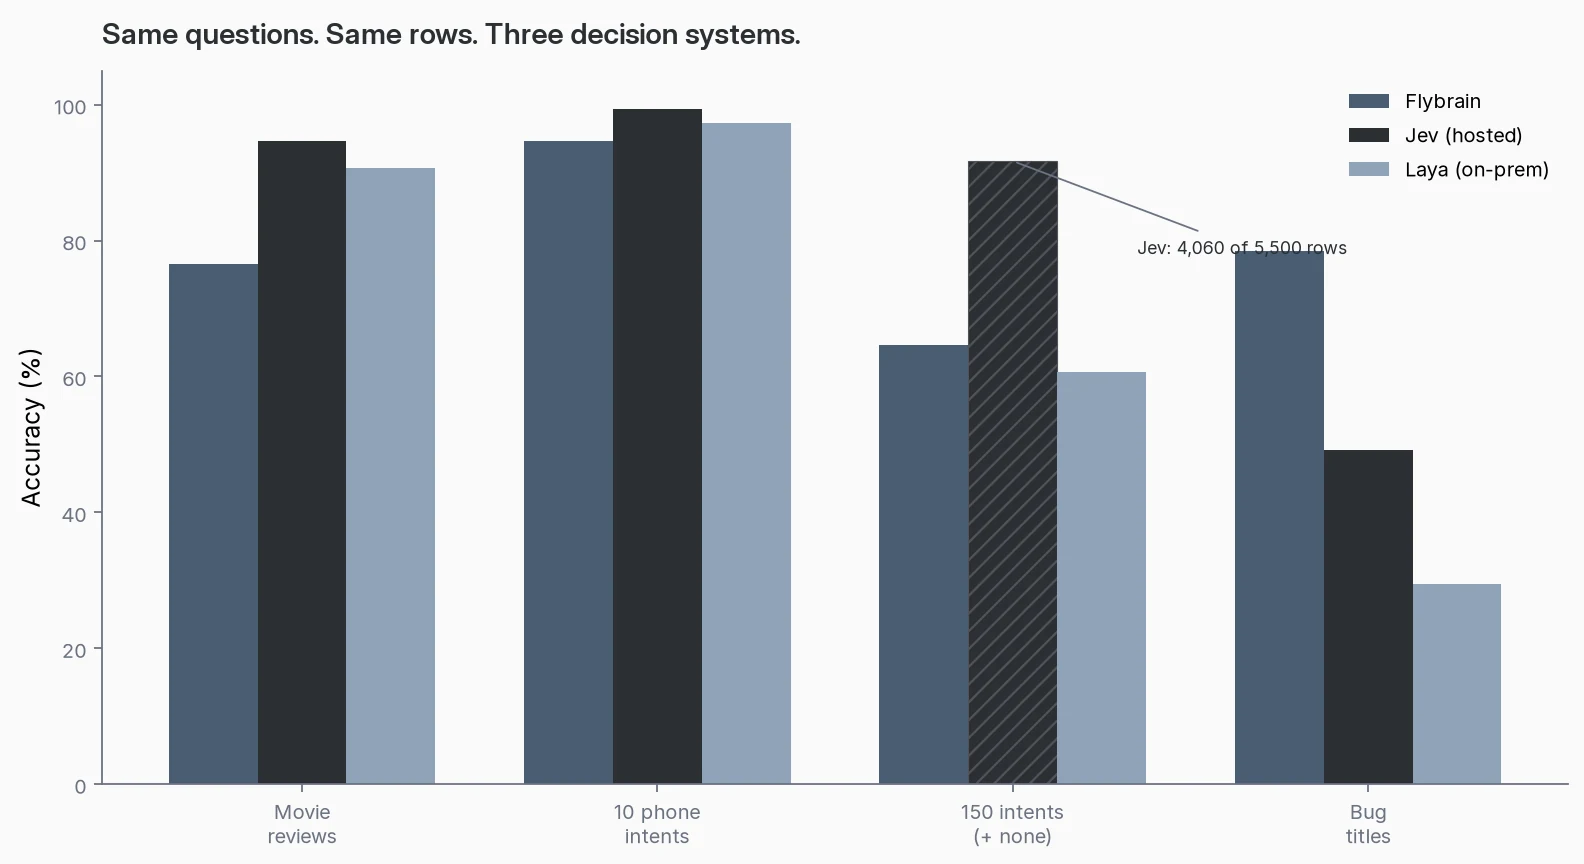
| Movie-review sentences | 872 | 76.5% | 94.6% | 90.6% |
| Ten phone intents | 300 | 94.7% | 99.3% | 97.3% |
| 150 intents + “none of these” | 5,500† | 64.6% | 91.7%† | 60.6% |
| Eclipse bug titles (severity) | 2,000 | 78.4% | 49.1% | 29.5% |
† Jev’s 150-intent number is on the 4,060 rows it finished before the hosted API stopped answering. Laya and Flybrain finished all 5,500.
Short English menus: hosted Jev leads, Laya is right behind it, both clear 90%+. Hard menu (151 options including “none of these”): Jev’s partial pass stays in the low 90s; the locals land in the 60s — the menu itself is the stress test. Bug titles from the title alone — weak signal, easy to shrug “normal” — Flybrain beats both cold. Jev’s whole metered spend for this A/B: about $0.48.
I’m not claiming Flybrain “beats Jev.” I’m claiming the scoreboard is more interesting than the timeline.
Speed is not a footnote
| Test | Flybrain | Jev | Laya |
|---|---|---|---|
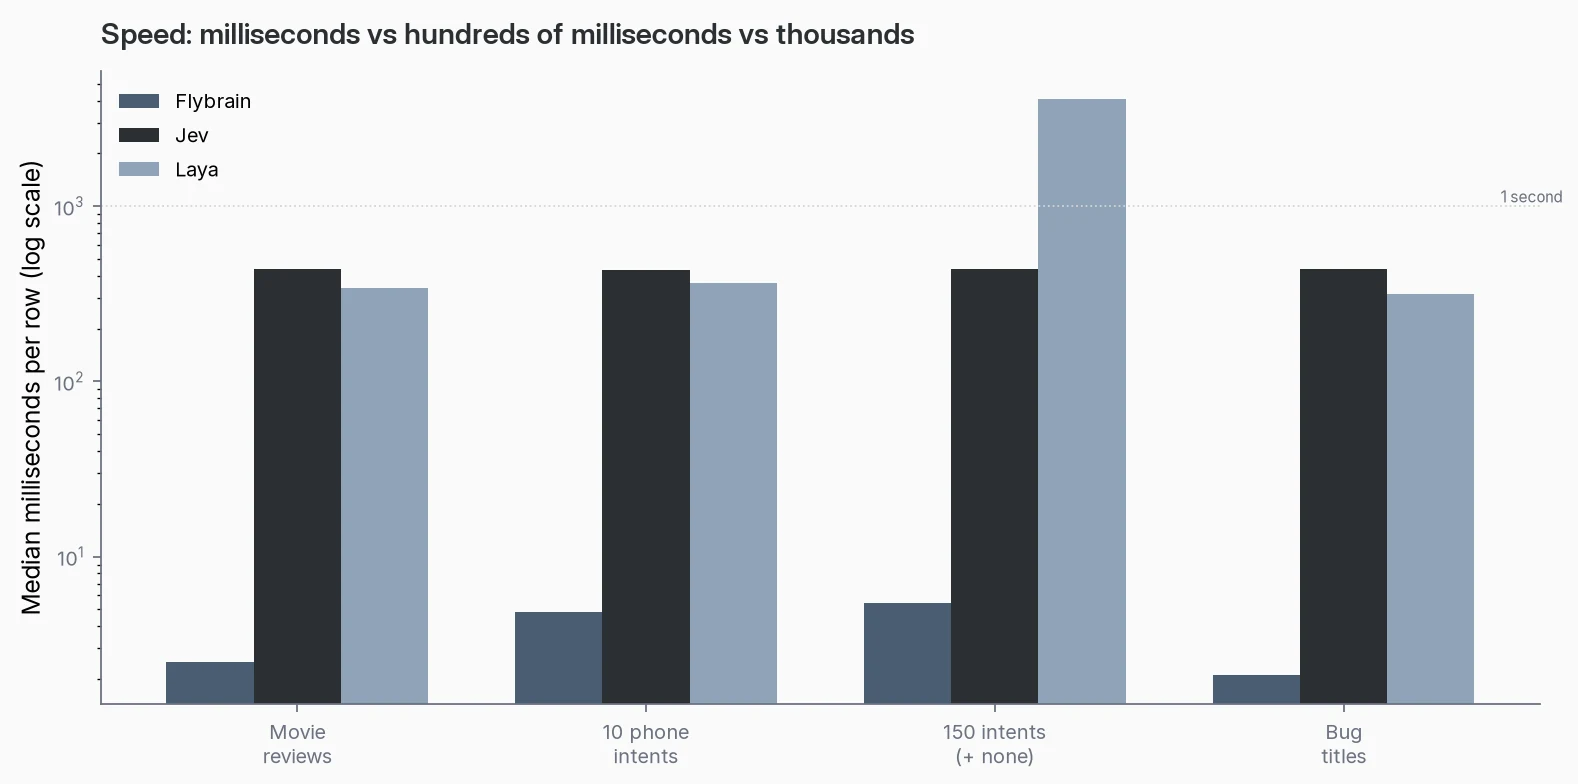
| Movie reviews | 2.5 | 436 | 340 |
| Ten intents | 4.8 | 434 | 365 |
| 150 intents | 5.4 | 435 | 4,063 |
| Bug titles | 2.1 | 438 | 314 |
Flybrain is roughly 100× faster on the short benches — ~2–5 ms vs ~340–440 ms. Small frozen network, not a large transformer call. Jev sits near 435 ms every time; that’s the hosted round trip. Laya matches that band on short menus, then spends ~4 seconds a row once the label list is 151 options long. Six hours of wall time to finish all 5,500.
Who finished the long bench
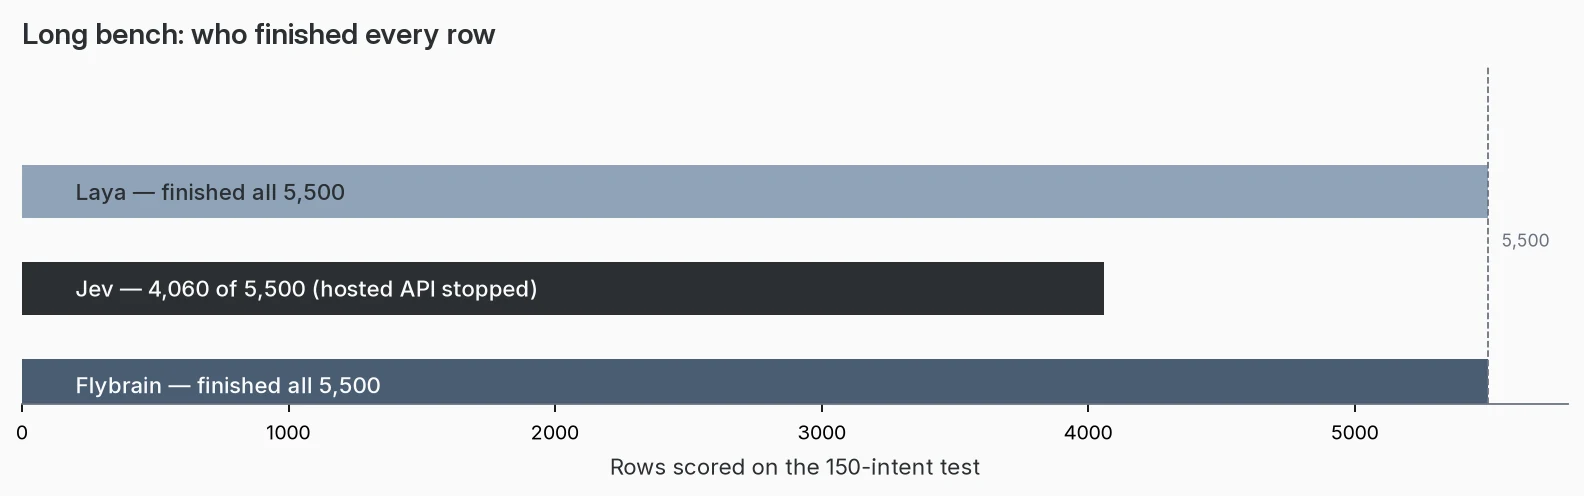
Laya finished. Flybrain finished. Jev stopped at 4,060 when the API stopped answering — mid-bench, not mid-design.
If your decision loop has to run overnight, finishability is a KPI. On-prem doesn’t inherit someone else’s daily ceiling. That isn’t a dunk on Venice. It’s what happened on the clock.
The $350 box
Everything on-prem — Flybrain and Laya — ran on one laptop: a Lenovo IdeaPad Slim 3 15IAN8 (model 82XB). Discount-bin story: about $350. Intel Core i3-N305, eight cores, up to ~3.8 GHz. 8 GB RAM. 256 GB NVMe. No GPU. Ubuntu. Jev never saw this machine; that arm was Venice’s API. The millisecond Flybrain times and the multi-hour Laya pass were both measured here.
What we actually asked
Four public tests. Situation text only. Fixed choice list.
1. Movie reviews (SST-2) — 872 rows. Stanford Sentiment Treebank via GLUE. Negative or positive.
What is the sentiment of this sentence?
2. Ten phone intents — 300 rows. CLINC utterances, ten intents only (alarm, calculator, date, definition, measurement conversion, spelling, time, timer, translate, weather). Thirty each. No “none of these.”
Which of these intents does the utterance express?
3. One hundred fifty intents + “none of these” — 5,500 rows. Full CLINC test split: 150 × 30 in-scope, plus 1,000 out-of-scope. Last choice is oos. Same question — now with 151 options. Laya gets the multilingual checkpoint with a window long enough to read the list. Jev gets the same 151-entry object in one request.
4. Eclipse bug titles — 2,000 rows. MSR 2013 titles only — no description. Severities folded to low / normal / high.
How severe is this bug, judging from the title alone?
Titles are thin. A model that parks on “normal” can post a fake-looking accuracy. That’s why Brier sits next to accuracy below.
Full scorecard
Brier is the sureness penalty: squared distance from a perfect “1 on the right answer, 0 on the others,” averaged over rows. Zero is perfect. Lower is better.
| Test | Rows | Flybrain acc | Flybrain Brier | Flybrain median s | Jev acc | Jev Brier | Jev median s | Laya acc | Laya Brier | Laya median s |
|---|---|---|---|---|---|---|---|---|---|---|
| Movie-review sentences | 872 | 0.765 | 0.324 | 0.0025 | 0.946 | 0.087 | 0.436 | 0.906 | 0.145 | 0.340 |
| Ten everyday requests | 300 | 0.947 | 0.165 | 0.0048 | 0.993 | 0.011 | 0.434 | 0.973 | 0.034 | 0.365 |
| 150 requests + none of these | 5500 (Jev 4060) | 0.646 | 0.954 | 0.0054 | 0.917 (partial) | 0.133 | 0.435 | 0.606 | 0.621 | 4.063 |
| Eclipse bug titles | 2000 | 0.784 | 0.364 | 0.0021 | 0.491 | 0.697 | 0.438 | 0.295 | 0.691 | 0.314 |
Jev input-token spend: about $0.483 at the published $0.042 / 1M input rate (output priced at zero).
Wall-clock this week (Jev / Laya):
| Test | Laya | Jev |
|---|---|---|
| Movie reviews (872) | ~5–6 min | ~40 min |
| Ten intents (300) | ~2 min | ~5 min |
| Bug titles (2,000) | ~10 min | ~33 min |
| 150 intents | ~6 h 13 min (all 5,500) | ~1 h 24 min (stopped at 4,060) |
Flybrain’s scored pass was earlier the same week on the same frozen files. Per-row times are in the table — ~2–5 ms.
Decision matrix — how I’d pick after this scoreboard
I’m not crowning a winner. I’m picking a modality for a constraint. After living this bakeoff, here’s the matrix I’d actually use:
| If this is the constraint… | I’d reach for… | Because the benches said… |
|---|---|---|
| Peak accuracy on short, clean menus (sentiment, ~10 intents) and a cloud round trip is fine | Hosted decision API (Jev) — Laya if you want almost-that accuracy on your own box | Jev 94.6% / 99.3%; Laya 90.6% / 97.3%; tightest Brier on Jev |
| Weak-signal labels where “normal” is an easy shrug — and you have a train split | Flybrain-style trained readout on a fixed body | Bug titles: Flybrain 78.4% vs Jev 49.1% / Laya 29.5% (both cold) |
| Milliseconds / high QPS on hardware you own | Flybrain | ~2–5 ms vs ~435 ms hosted — ~100× on a $350 CPU laptop |
| Multi-hour / multi-thousand-row pass that must finish without someone else’s API | On-prem (Laya or Flybrain) | 5,500 finished locally; hosted Jev stopped at 4,060 mid-bench |
| Huge menus (100+ options) without blowing the context window | Hosted Jev when it stays up; Laya only with the long-window checkpoint | 151-option menu is the stress; English 512-token Laya can’t hold it; long-window Laya finishes but ~4 s/row |
| Cheap one-shot evaluation — no new box to buy | Toss-up. Jev if you want the hosted frontier with a card; Flybrain or Laya if you’ve got idle hardware in the closet (we did this on a $350 CPU laptop) | Jev arm ~$0.48 API; Laya/Flybrain = power + time you already own. Tech shops usually have the second option sitting around |
Chat isn’t in this matrix. We didn’t score chat. Decision-shaped calls only — situation in, fixed menu out. Different shape, different bakeoff.
And Flybrain’s win conditions assume you can train that sticky-note head. No train split, no bug-title upset. Don’t hear “$350 laptop beats Jev” without that clause. I won’t write it that way either.
Close
Same questions. Three systems. A real fly connectome on a discount laptop, an open-weight decision model on the same box, and the hosted decision model everyone is posting about.
If my loop has to finish overnight on hardware I control, I’m not putting the long pass on a hosted API after this run. If I need peak accuracy on a short menu and I’m fine paying for the round trip, I reach for Jev. If I’ve got labels and I need milliseconds — or a weak-signal job where cold giants shrug — I reach for the fly readout.
That’s what these benches told me. Not a religion. A pick list.
What these things are (if you walked in cold)
Jev is Venice’s hosted decision model — not chat. Situation plus a fixed menu; chosen label plus probabilities. We called jev-latest on their public decisions API.
Laya is ConvAI’s open-weight decision model in the same shape. We ran the published checkpoints on the laptop — English for the short benches, multilingual when the menu got huge.
Flybrain is the larva connectome as the dynamical body. Real mapped neurons and synapses. Text in as activity. Decision out. That’s the “fly” in Flybrain / Fly Cast.
Appendix — exact decision objects
Situation text is the row’s text field and nothing else. Byte-for-byte:
Movie reviews
{"sentiment":{"type":"choice","instructions":"What is the sentiment of this sentence?","criteria":{"negative":"The sentence expresses negative sentiment.","positive":"The sentence expresses positive sentiment."}}}
Ten intents
{"intent":{"type":"choice","instructions":"Which of these intents does the utterance express?","criteria":{"alarm":"alarm","calculator":"calculator","date":"date","definition":"definition","measurement_conversion":"measurement_conversion","spelling":"spelling","time":"time","timer":"timer","translate":"translate","weather":"weather"}}}
150 intents + oos — same instruction shape; criteria keys are the 150 intent names from that split’s labels.json, alphabetical, then oos.
Bug titles
{"severity":{"type":"choice","instructions":"How severe is this bug, judging from the title alone?","criteria":{"low":"trivial or minor","normal":"normal","high":"major, critical, or blocker"}}}
Models as called
| Arm | Call | Where |
|---|---|---|
| Jev | POST https://api.venice.ai/api/v1/decisions, model jev-latest | Venice |
| Laya (short benches) | laya.load("convaiinnovations/laya") — English, 512-token context | On-prem (ngram), CPU |
| Laya (150 intents) | Multilingual checkpoint, max_len=4096, head_max_len=2048 | Same install |
Frozen test files (sha256)
| Task | Rows | sha256 |
|---|---|---|
| sst2 | 872 | c5d4733f9738b084e064836d98a27c7ddedc9bd3d8571a39fffb2d30eedd4005 |
| clinc10 | 300 | a229dfd59e5254930cc1053af12057ea00b5ce306666dac002562c759deb97fe |
| clinc150 | 5500 | a29710b72717f17a2514df8e9a5dfc5b37dbeb5ca1ee22f2b25fbd4a17918441 |
| bugsev | 2000 | 6715545ae7b01661bc1ff3bfafff476098061aedbd98832aeacf2972b9c023a6 |
Want the stack or the bakeoff walked through for your shop — hit us here.